import arviz as az
import numpy as np
import pymc as pm

rng = np.random.default_rng(6420)
2. Rats Example with Missing Data*#
This example goes further into dealing with missing data in PyMC, including in the predictor variables.
Adapted from Unit 8: ratsignorable1.odc, ratsignorable2.odc, and ratsinformative.odc.
Data can be found here.
Problem statement#
We had a previous example about dugongs that dealt with missing data in the observed data (y values). This example shows how to deal with missing data in the input data (x). It’s still pretty easy. You could look at it like creating another likelihood in the model, a very simple one where the observed data is x, and you use a single distribution to fill in the missing values (see x_imputed in the model below).
Original paper here.
Gelfand et al 1990 consider the problem of missing data, and delete the last observation of cases 6-10, the last two from 11-20, the last 3 from 21-25 and the last 4 from 26-30. The appropriate data file is obtained by simply replacing data values by NA (see below). The model specification is unchanged, since the distinction between observed and unobserved quantities is made in the data file and not the model specification.
x = np.array([8.0, 15.0, 22.0, 29.0, 36.0])
# import y data and create mask (missing data is represented as nan in the file)
y = np.loadtxt("../data/rats.txt")
y
array([[151., 199., 246., 283., 320.],
       [145., 199., 249., 293., 354.],
       [147., 214., 263., 312., 328.],
       [155., 200., 237., 272., 297.],
       [135., 188., 230., 280., 323.],
       [159., 210., 252., 298.,  nan],
       [141., 189., 231., 275.,  nan],
       [159., 201., 248., 297.,  nan],
       [177., 236., 285., 350.,  nan],
       [134., 182., 220., 260.,  nan],
       [160., 208., 261., 313.,  nan],
       [143., 188., 220.,  nan,  nan],
       [154., 200., 244.,  nan,  nan],
       [171., 221., 270.,  nan,  nan],
       [163., 216., 242.,  nan,  nan],
       [160., 207., 248.,  nan,  nan],
       [142., 187., 234.,  nan,  nan],
       [156., 203., 243.,  nan,  nan],
       [157., 212., 259.,  nan,  nan],
       [152., 203., 246.,  nan,  nan],
       [154., 205., 253.,  nan,  nan],
       [139., 190.,  nan,  nan,  nan],
       [146., 191.,  nan,  nan,  nan],
       [157., 211.,  nan,  nan,  nan],
       [132., 185.,  nan,  nan,  nan],
       [160.,  nan,  nan,  nan,  nan],
       [169.,  nan,  nan,  nan,  nan],
       [157.,  nan,  nan,  nan,  nan],
       [137.,  nan,  nan,  nan,  nan],
       [153.,  nan,  nan,  nan,  nan]])
Model 1#
This first model we only have missing data in our response variable (y). Notice that I made the shapes of alpha and beta (30, 1) instead of just 30. This is so that they broadcast correctly when combined (mu = alpha + beta * x). The NumPy docs have a helpful page about broadcasting.
prior_tau = 1e-2

with pm.Model() as m:
    alpha_c = pm.Normal("alpha_c", 0, tau=prior_tau)
    alpha_tau = pm.Gamma("alpha_tau", 0.01, 0.01)
    beta_c = pm.Normal("beta_c", 0, tau=prior_tau)
    beta_tau = pm.Gamma("beta_tau", 0.01, 0.01)

    alpha = pm.Normal(
        "alpha", alpha_c, tau=alpha_tau, shape=(30, 1)
    )  # (30, 1) for broadcasting
    beta = pm.Normal("beta", beta_c, tau=beta_tau, shape=(30, 1))
    lik_tau = pm.Gamma("lik_tau", 0.01, 0.01)
    sigma = pm.Deterministic("sigma", 1 / lik_tau**0.5)

    mu = alpha + beta * x

    pm.Normal("likelihood", mu, tau=lik_tau, observed=y)

    trace = pm.sample(
        5000,
        tune=5000,
        target_accept=0.95,
        random_seed=rng,
    )
az.summary(
    trace,
    ci_prob=0.95,
    var_names=["alpha_c", "alpha_tau", "beta_c", "beta_tau", "sigma"],
    kind="stats",
)
| mean | sd | eti95_lb | eti95_ub | |
|---|---|---|---|---|
| alpha_c | 95 | 3.1 | 89 | 100 |
| alpha_tau | 0.016 | 0.044 | 0.0039 | 0.042 |
| beta_c | 6.7 | 0.16 | 6.4 | 7.1 |
| beta_tau | 2.9 | 1.3 | 1.2 | 6.1 |
| sigma | 6.1 | 0.69 | 4.9 | 7.6 |
Model 2: Imputing missing predictor variable data#
This is the same model, except we now have missing x data.
x_miss = np.array([8.0, 15.0, 22.0, np.nan, 36.0])
x_miss
array([ 8., 15., 22., nan, 36.])
prior_tau = 1e-2

with pm.Model() as m:
    alpha_c = pm.Normal("alpha_c", 0, tau=prior_tau)
    alpha_tau = pm.Gamma("alpha_tau", 0.01, 0.01)
    beta_c = pm.Normal("beta_c", 0, tau=prior_tau)
    beta_tau = pm.Gamma("beta_tau", 0.01, 0.01)

    alpha = pm.Normal("alpha", alpha_c, tau=alpha_tau, shape=(30, 1))
    beta = pm.Normal("beta", beta_c, tau=beta_tau, shape=(30, 1))
    lik_tau = pm.Gamma("lik_tau", 0.01, 0.01)
    sigma = pm.Deterministic("sigma", 1 / lik_tau**0.5)

    x_imputed = pm.Normal("x_imputed", mu=20, sigma=5, observed=x_miss)

    mu = alpha + beta * x_imputed

    pm.Normal("likelihood", mu, tau=lik_tau, observed=y)

    trace_2 = pm.sample(
        5000,
        tune=5000,
        # init="jitter+adapt_diag_grad",
        target_accept=0.95,
        random_seed=rng,
    )
az.summary(trace_2, ci_prob=0.95, var_names=["x_imputed"])
/Users/aaron/miniforge3/envs/pymc_f26/lib/python3.14/site-packages/arviz_stats/base/diagnostics.py:90: RuntimeWarning: invalid value encountered in scalar divide
  (between_chain_variance / within_chain_variance + num_samples - 1) / (num_samples)
/Users/aaron/miniforge3/envs/pymc_f26/lib/python3.14/site-packages/arviz_stats/base/diagnostics.py:313: RuntimeWarning: invalid value encountered in scalar divide
  varsd = varvar / evar / 4
/Users/aaron/miniforge3/envs/pymc_f26/lib/python3.14/site-packages/arviz_stats/base/diagnostics.py:313: RuntimeWarning: invalid value encountered in scalar divide
  varsd = varvar / evar / 4
| mean | sd | eti95_lb | eti95_ub | ess_bulk | ess_tail | r_hat | mcse_mean | mcse_sd | |
|---|---|---|---|---|---|---|---|---|---|
| x_imputed[0] | 8 | 0 | 8 | 8 | 20000 | 20000 | nan | 0 | nan |
| x_imputed[1] | 15 | 0 | 15 | 15 | 20000 | 20000 | nan | 0 | nan |
| x_imputed[2] | 22 | 0 | 22 | 22 | 20000 | 20000 | nan | 0 | nan |
| x_imputed[3] | 29.272 | 0.386 | 29 | 30 | 7148 | 2443 | 1.00 | 0.0046 | 0.0033 |
| x_imputed[4] | 36 | 0 | 36 | 36 | 20000 | 20000 | nan | 0 | nan |
Note
The above error in the output happens because only one of these was actually imputed. The rest are just fixed data, so diagnostics like Rhat checking variance between chains don’t work. You can get rid of these warnings by either adding “_unobserved” to the var_name or requesting kind="stats".
az.summary(trace_2, ci_prob=0.95, var_names=["x_imputed_unobserved"])
| mean | sd | eti95_lb | eti95_ub | ess_bulk | ess_tail | r_hat | mcse_mean | mcse_sd | |
|---|---|---|---|---|---|---|---|---|---|
| x_imputed_unobserved[0] | 29.272 | 0.386 | 29 | 30 | 7148 | 2443 | 1.00 | 0.0046 | 0.0033 |
az.summary(trace_2, ci_prob=0.95, var_names=["x_imputed"], kind="stats")
| mean | sd | eti95_lb | eti95_ub | |
|---|---|---|---|---|
| x_imputed[0] | 8 | 0 | 8 | 8 |
| x_imputed[1] | 15 | 0 | 15 | 15 |
| x_imputed[2] | 22 | 0 | 22 | 22 |
| x_imputed[3] | 29 | 0.39 | 29 | 30 |
| x_imputed[4] | 36 | 0 | 36 | 36 |
az.summary(
    trace_2,
    ci_prob=0.95,
    var_names=["alpha_c", "beta_c", "alpha_tau", "beta_tau", "lik_tau"],
    kind="stats",
)
| mean | sd | eti95_lb | eti95_ub | |
|---|---|---|---|---|
| alpha_c | 96 | 3.1 | 89 | 100 |
| beta_c | 6.7 | 0.17 | 6.4 | 7.1 |
| alpha_tau | 0.039 | 0.3 | 0.0039 | 0.045 |
| beta_tau | 3 | 1.3 | 1.3 | 6.3 |
| lik_tau | 0.029 | 0.0064 | 0.017 | 0.042 |
Model 3: Non-ignorable missingness#
Odds of missingness increases approx. at a rate of 1% with increasing the weight.
y = np.atleast_2d(
    np.array([177.0, 236.0, 285.0, 350.0, -1])
)  # original value was 320
y = np.ma.masked_values(y, value=-1)  # create masked array
# y.mask is equivalent to the "miss" array from the professor's example
miss = y.mask
x = np.array([8.0, 15.0, 22.0, 29.0, 36.0])
t = 0.1
s = 1 / t  # convert BUGS dlogis tau to s for pymc
b = np.log(1.01)

with pm.Model() as m:
    a = pm.Logistic("a", mu=0, s=s)
    # adjusting alpha, beta, sigma priors to be weakly informative compared
    # to old flat priors in order to get rid of divergences.
    alpha = pm.Normal("alpha", 0, 10)
    beta = pm.Normal("beta", 0, 10)
    sigma = pm.Exponential("sigma", 0.01)

    mu = pm.Deterministic("mu", alpha + beta * x)
    y_imputed = pm.Normal("likelihood", mu, sigma, observed=y)

    p = pm.Deterministic("p", pm.math.invlogit(a + b * y_imputed))
    pm.Bernoulli("missing", p=p, observed=miss)

    trace_3 = pm.sample(
        5000,
        tune=4000,
        # init="adapt_diag",
        target_accept=0.95,
        random_seed=rng,
    )
pm.model_to_graphviz(m)
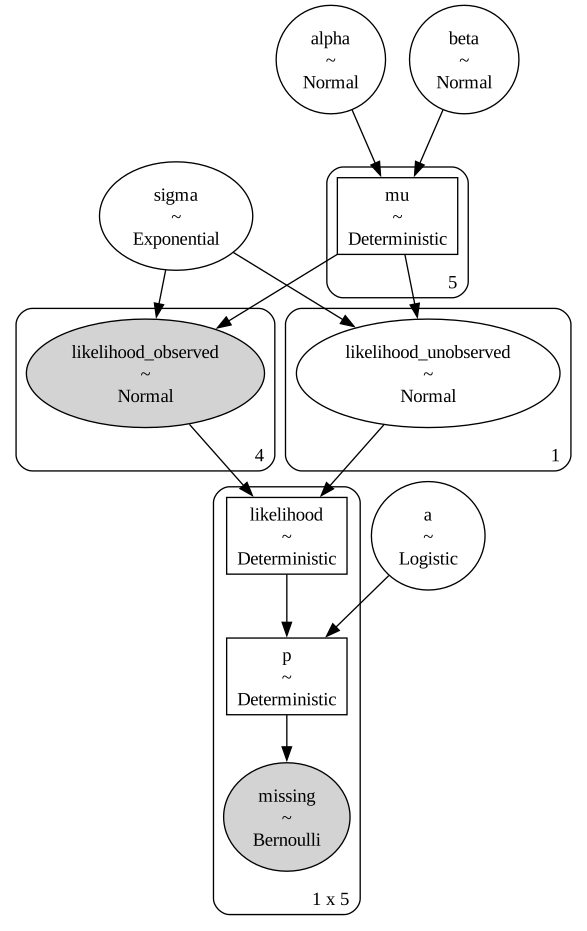
az.summary(trace_3, ci_prob=0.95, kind="stats")
| mean | sd | eti95_lb | eti95_ub | |
|---|---|---|---|---|
| a | -5.2 | 1.5 | -8.7 | -2.7 |
| alpha | 2.7 | 10 | -17 | 23 |
| beta | 13 | 1.9 | 9.7 | 17 |
| likelihood_unobserved[0] | 510 | 100 | 340 | 750 |
| sigma | 69 | 37 | 29 | 160 |
| mu[0] | 110 | 16 | 77 | 140 |
| mu[1] | 200 | 27 | 150 | 260 |
| mu[2] | 290 | 39 | 220 | 380 |
| mu[3] | 390 | 52 | 280 | 500 |
| mu[4] | 480 | 65 | 350 | 620 |
| likelihood[0, 0] | 180 | 0 | 180 | 180 |
| likelihood[0, 1] | 240 | 0 | 240 | 240 |
| likelihood[0, 2] | 280 | 0 | 280 | 280 |
| likelihood[0, 3] | 350 | 0 | 350 | 350 |
| likelihood[0, 4] | 510 | 100 | 340 | 750 |
| p[0, 0] | 0.064 | 0.078 | 0.001 | 0.29 |
| p[0, 1] | 0.1 | 0.11 | 0.0018 | 0.42 |
| p[0, 2] | 0.15 | 0.15 | 0.0029 | 0.55 |
| p[0, 3] | 0.23 | 0.19 | 0.0056 | 0.7 |
| p[0, 4] | 0.49 | 0.27 | 0.027 | 0.95 |
%load_ext watermark
%watermark -n -u -v -iv -p pytensor
Last updated: Mon, 19 Oct 2026

Python implementation: CPython
Python version       : 3.14.7
IPython version      : 9.16.1

pytensor: 3.3.0

arviz: 1.3.0
numpy: 2.4.6
pymc : 6.3.1