import arviz as az
import pandas as pd
import pymc as pm
from pymc.math import dot, invlogit
import numpy as np

rng = np.random.default_rng(6420)
15. GLM Examples*#
Arrhythmia#
A logistic regression example, adapted from Unit 7: arrhythmia.odc.
Data descriptions#
I mirrored the data here.
Variable ID |
Name |
Description |
|---|---|---|
Y |
Fibrillation |
Outcome variable: presence of fibrillation. |
X1 |
Age |
Age of the patient. |
X2 |
Aortic Cross Clamp Time |
Duration of time the aortic valve is clamped during surgery. |
X3 |
Cardiopulmonary Bypass Time |
Bypass of the heart and lungs. Involves diverting blood through a heart-lung machine, which performs the functions of the heart and lungs. |
X4 |
ICU Time |
Time spent in the Intensive Care Unit. |
X5 |
Avg Heart Rate |
Average heart rate of the patient. |
X6 |
Left Ventricle Ejection Fraction |
Measure of how well the left ventricle pumps blood out to the body. |
X7 |
Hypertension |
Binary: Presence (1) or absence (0) of high blood pressure. |
X8 |
Gender |
Binary: 1 for female; 0 for male. |
X9 |
Diabetes |
Binary: Presence (1) or absence (0) of diabetes. |
X10 |
Previous MI |
Binary: Presence (1) or absence (0) of a previous myocardial infarction (heart attack). |
Background#
Patients who undergo Coronary Artery Bypass Graft Surgery (CABG) have an approximate 19–40% chance of developing atrial fibrillation (AF). AF can lead to the formation of blood clots, resulting in increased in-hospital mortality, strokes, and longer hospital stays. While drugs can prevent this condition, they are expensive and can be dangerous if not warranted. Ideally, identifying several risk factors that indicate an increased risk of developing AF could save lives and money by showing which patients need pharmacological intervention. Researchers have begun collecting data such as demographics, heart rate, cholesterol, and operation time from CABG patients during their hospital stays. They have also recorded which patients developed AF. The goal now is to identify the data points that signal a high risk of AF. In the past, factors such as age, hypertension, and body surface area (BSA) have been useful indicators, although they have not provided a satisfactory solution on their own.
Fibrillation occurs when the heart muscle begins a quivering motion instead of maintaining a normal, healthy pumping rhythm. Fibrillation can affect either the atrium (atrial fibrillation) or the ventricle (ventricular fibrillation); the latter is imminently life-threatening.
Atrial fibrillation involves quivering, chaotic motion in the upper chambers of the heart, known as the atria. It is often linked to serious underlying medical conditions and should be evaluated by a physician. Although it is not typically a medical emergency, it still requires medical attention.
Ventricular fibrillation occurs in the ventricles (lower chambers) of the heart and is always a medical emergency. If left untreated, ventricular fibrillation (VF, or V-fib) can lead to death within minutes. When the heart enters V-fib, effective blood pumping ceases. V-fib is considered a form of cardiac arrest, and an individual experiencing it will not survive unless immediate cardiopulmonary resuscitation (CPR) and defibrillation are administered.
Model#
This is a logistic regression model. We consider each patient’s outcome a single Bernoulli event.
where \(k\) is the number of predictors and \(g(\cdot)\) is the logit function: \(\text{logit}(p) = \ln\left(\frac{p}{1-p}\right)\), and its inverse \(g^{-1}(\cdot)\) is the logistic function: \(\text{logistic}(x) = \frac{1}{1 + e^{-x}}\).
If your data is in an aggregated format, you should consider going with a Binomial likelihood. The model can be equivalently stated this way:
data_df = pd.read_csv("../data/arrhythmia.csv")
data_df.info()
X = data_df.iloc[:, 1:]
y = data_df["Fibrillation"]
<class 'pandas.DataFrame'>
RangeIndex: 81 entries, 0 to 80
Data columns (total 11 columns):
 #   Column                         Non-Null Count  Dtype
---  ------                         --------------  -----
 0   Fibrillation                   81 non-null     float64
 1   Age                            81 non-null     float64
 2   AorticCrossClampTime           81 non-null     float64
 3   CardiopulmonaryBypassTime      81 non-null     float64
 4   ICUTime                        81 non-null     float64
 5   AvgHeartRate                   81 non-null     float64
 6   LeftVentricleEjectionFraction  81 non-null     float64
 7   Hypertension                   81 non-null     float64
 8   Gender                         81 non-null     float64
 9   Diabetes                       81 non-null     float64
 10  PreviousMI                     81 non-null     float64
dtypes: float64(11)
memory usage: 7.1 KB
data_df.describe()
| Fibrillation | Age | AorticCrossClampTime | CardiopulmonaryBypassTime | ICUTime | AvgHeartRate | LeftVentricleEjectionFraction | Hypertension | Gender | Diabetes | PreviousMI | |
|---|---|---|---|---|---|---|---|---|---|---|---|
| count | 81.000000 | 81.000000 | 81.000000 | 81.000000 | 81.000000 | 81.000000 | 81.000000 | 81.000000 | 81.000000 | 81.000000 | 81.000000 |
| mean | 0.345679 | 66.654321 | 81.753086 | 131.123457 | 16.148716 | 85.683951 | 56.401235 | 0.666667 | 0.308642 | 0.419753 | 0.469136 |
| std | 0.478552 | 10.429718 | 30.322241 | 56.196170 | 3.672736 | 11.847557 | 13.634153 | 0.474342 | 0.464811 | 0.496593 | 0.502156 |
| min | 0.000000 | 44.000000 | 0.000000 | 0.000000 | 2.000000 | 50.000000 | 18.000000 | 0.000000 | 0.000000 | 0.000000 | 0.000000 |
| 25% | 0.000000 | 61.000000 | 67.000000 | 109.000000 | 13.500000 | 77.200000 | 50.000000 | 0.000000 | 0.000000 | 0.000000 | 0.000000 |
| 50% | 0.000000 | 69.000000 | 82.000000 | 128.000000 | 16.000000 | 86.700000 | 59.000000 | 1.000000 | 0.000000 | 0.000000 | 0.000000 |
| 75% | 1.000000 | 73.000000 | 98.000000 | 148.000000 | 19.000000 | 94.800000 | 65.000000 | 1.000000 | 1.000000 | 1.000000 | 1.000000 |
| max | 1.000000 | 88.000000 | 193.000000 | 487.000000 | 23.000000 | 111.800000 | 82.000000 | 1.000000 | 1.000000 | 1.000000 | 1.000000 |
Our predictors have very different scales. With non-informative priors as the professor uses in the BUGS model, the coefficients should have no trouble fitting the data. However, since PyMC uses a different sampling algorithm it seems to be having trouble with the shape of the posterior. Actually, this used to work fine in PyMC (as of version 5.1.2, at least), but students in Fall 2023 discovered that PyMC could no longer sample this model without divergences (using version 5.9.0 or above).
with pm.Model() as m:
    X_data = pm.Data("X_data", X)
    y_data = pm.Data("y_data", y)

    alpha = pm.Normal("alpha", mu=0, sigma=10)
    betas = pm.Normal("beta", mu=0, sigma=5, shape=X.shape[1])

    p = invlogit(alpha + dot(X_data, betas))

    pm.Bernoulli("y", p=p, observed=y_data)

    trace = pm.sample(5000, random_seed=rng)
az.summary(trace, ci_prob=0.95)
| mean | sd | eti95_lb | eti95_ub | ess_bulk | ess_tail | r_hat | mcse_mean | mcse_sd | |
|---|---|---|---|---|---|---|---|---|---|
| alpha | -10.6 | 4.26 | -19 | -2.6 | 5373 | 7314 | 1.00 | 0.058 | 0.042 |
| beta[0] | 0.172 | 0.0453 | 0.091 | 0.27 | 6280 | 7761 | 1.00 | 0.00058 | 0.00043 |
| beta[1] | 0.0278 | 0.0244 | -0.018 | 0.077 | 7664 | 9114 | 1.00 | 0.00028 | 0.0002 |
| beta[2] | -0.0208 | 0.0158 | -0.054 | 0.0072 | 8161 | 10047 | 1.00 | 0.00018 | 0.00013 |
| beta[3] | -0.159 | 0.094 | -0.35 | 0.023 | 13489 | 12623 | 1.00 | 0.00081 | 0.00059 |
| beta[4] | -0.0022 | 0.0298 | -0.061 | 0.057 | 7548 | 9293 | 1.00 | 0.00034 | 0.00025 |
| beta[5] | 0.0182 | 0.0272 | -0.035 | 0.072 | 11718 | 12620 | 1.00 | 0.00025 | 0.00018 |
| beta[6] | -0.619 | 0.646 | -1.9 | 0.64 | 24387 | 15102 | 1.00 | 0.0041 | 0.003 |
| beta[7] | -0.309 | 0.677 | -1.7 | 1 | 26443 | 16088 | 1.00 | 0.0042 | 0.003 |
| beta[8] | 1.156 | 0.651 | -0.089 | 2.5 | 18287 | 14063 | 1.00 | 0.0048 | 0.0035 |
| beta[9] | 0.316 | 0.67 | -0.98 | 1.6 | 21837 | 16770 | 1.00 | 0.0045 | 0.0032 |
m.to_graphviz()
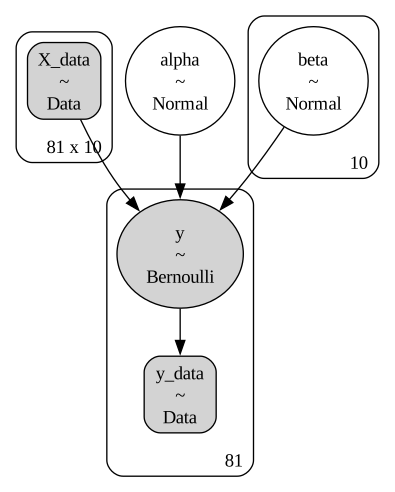
Previously this model had tons of divergences. We fixed the divergences by standardizing our data. Andrew Gelman Gelman [2008] suggests standardizing by two standard deviations.
With the PyMC v6 update, the divergences seem to have gone away, but I’m leaving the code here anyways.
def standardize(X_df: pd.DataFrame) -> pd.DataFrame:
    """
    Standardize input variables by 2 std dev.

    See https://stat.columbia.edu/~gelman/research/published/standardizing7.pdf.
    """
    # probably don't want to standardize binary predictors
    continuous = [col for col in X_df if X_df[col].nunique() > 2]
    X_standardized = X_df.copy()
    # find and store means and std, then standardize
    X_standardized[continuous] = (
        X_df[continuous] - X_df[continuous].mean()
    ) / (2 * X_df[continuous].std())

    return X_standardized
X_std = standardize(data_df.iloc[:, 1:])
with m:
    pm.set_data({"X_data": X_std})
    trace_std = pm.sample(5000, random_seed=rng)
NUTS[nutpie]: [alpha, beta]
az.summary(trace_std, ci_prob=0.95)
| mean | sd | eti95_lb | eti95_ub | ess_bulk | ess_tail | r_hat | mcse_mean | mcse_sd | |
|---|---|---|---|---|---|---|---|---|---|
| alpha | -1.41 | 0.73 | -2.9 | -0.011 | 9767 | 10689 | 1.00 | 0.0074 | 0.0054 |
| beta[0] | 3.72 | 0.98 | 2 | 5.8 | 16443 | 14101 | 1.00 | 0.0078 | 0.0059 |
| beta[1] | 1.6 | 1.37 | -1.1 | 4.4 | 8660 | 10043 | 1.00 | 0.015 | 0.011 |
| beta[2] | -2.12 | 1.58 | -5.4 | 0.71 | 8827 | 10407 | 1.00 | 0.017 | 0.012 |
| beta[3] | -1.078 | 0.68 | -2.4 | 0.25 | 22761 | 15623 | 1.00 | 0.0045 | 0.0033 |
| beta[4] | 0.11 | 0.723 | -1.3 | 1.5 | 20241 | 15346 | 1.00 | 0.0051 | 0.0037 |
| beta[5] | 0.63 | 0.744 | -0.81 | 2.1 | 17067 | 15902 | 1.00 | 0.0057 | 0.0042 |
| beta[6] | -0.62 | 0.657 | -1.9 | 0.65 | 13604 | 13448 | 1.00 | 0.0056 | 0.004 |
| beta[7] | -0.298 | 0.669 | -1.6 | 1 | 21322 | 15959 | 1.00 | 0.0046 | 0.0033 |
| beta[8] | 1.25 | 0.677 | -0.051 | 2.6 | 14972 | 13445 | 1.00 | 0.0056 | 0.004 |
| beta[9] | 0.39 | 0.679 | -0.92 | 1.7 | 13777 | 13939 | 1.00 | 0.0058 | 0.0042 |
Ants#
An example of Poisson regression, adapted from Unit 7: ants.odc.
Data description#
Data can be found here.
The data discussed in Gotelli and Ellison (2002) provide the ant species richness (number of ant species) found in 64-square-meter sampling grids in 22 forests (coded as 1) and 22 bogs (coded as 2) surrounding the forests in Connecticut, Massachusetts, and Vermont. The sites span 3 degrees of latitude in New England. There are 44 observations on four variables (columns in data set):
Ants: number of species,
Habitat: forests (1) and bogs (2),
Elevation: in meters above sea level.
(a) Using Poisson regression, model the number of ant species (Ants) with covariates Habitat and Elevation.
(b) For a sampling grid unit located in a forest at the elevation of 100 m how many species the model from (a) predicts? For the model coefficients and the prediction report 95% credible sets.
Poisson regression model#
For Poisson regression our link function \(g(\cdot)\) is the natural logarithm and its inverse \(g^{-1}(\cdot)\) is the exponential function.
data = pd.read_csv("../data/ants.csv")
data.info()
<class 'pandas.DataFrame'>
RangeIndex: 44 entries, 0 to 43
Data columns (total 3 columns):
 #   Column     Non-Null Count  Dtype
---  ------     --------------  -----
 0   ants       44 non-null     int64
 1   habitat    44 non-null     int64
 2   elevation  44 non-null     int64
dtypes: int64(3)
memory usage: 1.2 KB
For some reason, nutpie struggles to sample this model. Switching back to the PyMC sampler works. We may need to adjust this model in the future.
with pm.Model() as m:
    ant_species = pm.Data("ant_species", data["ants"].to_numpy())
    habitat = pm.Data("habitat", data["habitat"].to_numpy())
    elevation = pm.Data("elevation", data["elevation"].to_numpy())

    beta0 = pm.Normal("beta0_intercept", mu=0, tau=0.01)
    beta1 = pm.Normal("beta1_habitat", mu=0, tau=0.01)
    beta2 = pm.Normal("beta2_elevation", mu=0, tau=0.01)

    μ = pm.math.exp(beta0 + beta1 * habitat + beta2 * elevation)

    y = pm.Poisson(
        "y", mu=μ, observed=ant_species, shape=habitat.shape[0]
    )  # assuming elevation and habitat have same shape

    trace = pm.sample(
        5000,
        tune=1000,
        nuts_sampler="pymc",
        random_seed=rng,
    )
az.summary(trace)
| mean | sd | eti89_lb | eti89_ub | ess_bulk | ess_tail | r_hat | mcse_mean | mcse_sd | |
|---|---|---|---|---|---|---|---|---|---|
| beta0_intercept | 3.166 | 0.184 | 2.9 | 3.5 | 7289 | 8115 | 1.00 | 0.0022 | 0.0015 |
| beta1_habitat | -0.635 | 0.119 | -0.82 | -0.44 | 7890 | 8533 | 1.00 | 0.0013 | 0.00095 |
| beta2_elevation | -0.001487 | 0.000372 | -0.0021 | -0.00089 | 10062 | 9354 | 1.00 | 3.7e-06 | 2.7e-06 |
# prediction
with m:
    pm.set_data({"habitat": [1], "elevation": [100]})
    ppc = pm.sample_posterior_predictive(trace, predictions=True)
ppc.predictions
<xarray.DataTree 'predictions'>
Group: /predictions
    Dimensions:  (chain: 4, draw: 5000, y_dim_0: 1)
    Coordinates:
      * chain    (chain) int64 32B 0 1 2 3
      * draw     (draw) int64 40kB 0 1 2 3 4 5 6 ... 4994 4995 4996 4997 4998 4999
      * y_dim_0  (y_dim_0) int64 8B 0
    Data variables:
        y        (chain, draw, y_dim_0) int64 160kB 11 15 13 12 8 ... 13 10 14 10 15
    Attributes:
        created_at:                 2026-10-19T04:28:26.163996+00:00
        creation_library:           ArviZ
        creation_library_version:   1.3.0
        creation_library_language:  Python
        inference_library:          pymc
        inference_library_version:  6.3.1
sample_dims: ['chain', 'draw']az.summary(ppc.predictions, group="predictions")
| mean | sd | eti89_lb | eti89_ub | ess_bulk | ess_tail | r_hat | mcse_mean | mcse_sd | |
|---|---|---|---|---|---|---|---|---|---|
| y[0] | 10.87 | 3.4 | 6 | 17 | 19535 | 19188 | 1.00 | 0.024 | 0.018 |
%load_ext watermark
%watermark -n -u -v -iv -p pytensor
Last updated: Sun, 18 Oct 2026

Python implementation: CPython
Python version       : 3.14.7
IPython version      : 9.16.1

pytensor: 3.3.0

arviz   : 1.3.0
numpy   : 2.4.6
pandas  : 3.0.5
pymc    : 6.3.1
pytensor: 3.3.0