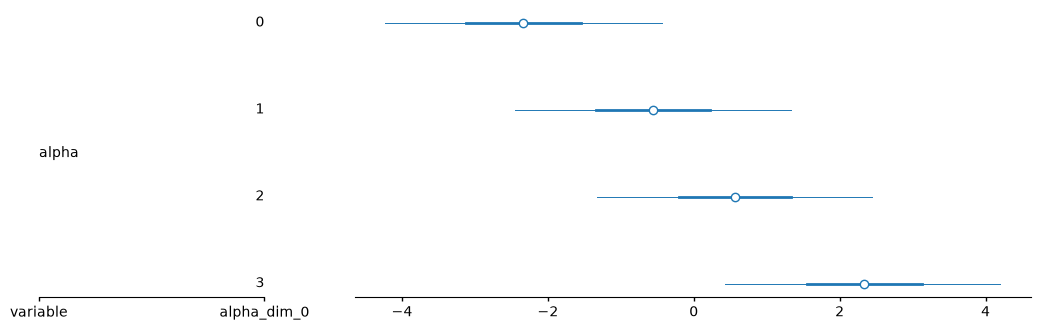
Supplementary Exercises#

Warning

This page contains solutions! We recommend attempting each problem before peeking.

1. Beetles (Bliss Data)#

In his 1935 paper, Bliss provides a table showing a number of flour beetles killed after 5 hours of exposure to gaseous carbon disulfide at various concentrations. This data set has since been used extensively by statisticians to illustrate and compare models for binary and binomial data.

Use logistic regression on the following data:

x = np.array([1.6907, 1.7242, 1.7552, 1.7842, 1.8113, 1.8369, 1.8610, 1.8839])
n = np.array([59, 60, 62, 56, 63, 59, 62, 60])
y = np.array([6, 13, 18, 28, 52, 53, 61, 60])

Use one of the logit, probit, cloglog, loglog, or cauchyit link functions.

Hide code cell content

import pymc as pm
import arviz as az
import pandas as pd
import numpy as np
from pymc.math import exp, invlogit, invprobit, arctan

rng = np.random.default_rng(6420)


# Complementary log-log transformation
def invcloglog(x):
    return 1 - exp(-exp(x))


# Log-log transformation
def invloglog(x):
    return exp(-exp(-x))


# Cauchit transformation
def invcauchit(x):
    return 0.5 + (1 / np.pi) * arctan(x)


x = np.array([1.6907, 1.7242, 1.7552, 1.7842, 1.8113, 1.8369, 1.8610, 1.8839])
n = np.array([59, 60, 62, 56, 63, 59, 62, 60])
y = np.array([6, 13, 18, 28, 52, 53, 61, 60])

with pm.Model() as m:
    x_data = pm.Data("concentration", x)

    beta0 = pm.Normal("beta0", 0, 100)
    beta1 = pm.Normal("beta1", 0, 100)

    # Uncomment desired link function
    p = invlogit(beta0 + beta1 * x_data)  # logit
    # p = invprobit(beta0 + beta1 * x_data)  # probit
    # p = invcloglog(beta0 + beta1 * x_data)  # cloglog
    # p = invloglog(beta0 + beta1 * x_data)  # loglog
    # p = invcauchit(beta0 + beta1 * x_data)  # cauchyit

    pm.Binomial("likelihood", n=n, p=p, observed=y)

    trace = pm.sample(5000, random_seed=rng)

az.summary(trace, kind="stats")
NUTS[nutpie]: [beta0, beta1]

mean sd eti89_lb eti89_ub
beta0 -61 5.1 -69 -53
beta1 34 2.9 30 39

2. Vasoconstriction#

The data give the presence or absence (\(y_i = 1\) or \(0\)) of vasoconstriction in the skin of the fingers following inhalation of a certain volume of air (\(v_i\)) at a certain average rate (\(r_i\)). Total number of records is 39. The candidate models for analyzing the relationship are the usual logit, probit, cloglog, loglog, and cauchyit models.

Data is available for download in csv format here.

  1. Transform covariates \(v\) and \(r\) as:

\[ x_1 = \log(10 \times v), \quad x_2 = \log(10 \times r) \]
  1. Using a PPL, estimate posterior means for coefficients in the logit model. Use noninformative priors on all coefficients.

  2. For a subject with \(v = r = 1.5\), find the probability of vasoconstriction.

  3. Which of the five links: logit, probit, cloglog, loglog, and cauchyit, has the smallest deviance? An example for use of the five links is in Question 1, above. Uncomment and run one link at a time.

Hide code cell content

import pymc as pm
import arviz as az
import pandas as pd
import numpy as np
from pymc.math import dot, invlogit, invprobit, log, sum, exp, arctan

rng = np.random.default_rng(6420)

# Read data and transform x's
data = pd.read_csv("../data/vasoconstriction.csv")
data["x1"] = np.log(10 * data["v"])
data["x2"] = np.log(10 * data["r"])


# Complementary log-log transformation
def invcloglog(x):
    return 1 - exp(-exp(x))


# Log-log transformation
def invloglog(x):
    return exp(-exp(-x))


# Cauchit transformation
def invcauchit(x):
    return 0.5 + (1 / np.pi) * arctan(x)


# New data point
new_data = np.array([[np.log(10 * 1.5), np.log(10 * 1.5)]])

with pm.Model() as m:
    # Data
    X_data = pm.Data("X_data", data[["x1", "x2"]])
    y_data = pm.Data("y_data", data["y"])

    # Coefficient priors
    alpha = pm.Normal("alpha", mu=0, sigma=1000)
    betas = pm.Normal("beta", mu=0, sigma=1000, shape=X_data.shape[1])

    # Bernoulli Regression
    p = invlogit(alpha + dot(X_data, betas))
    # p = invprobit(alpha + dot(X_data, betas))
    # p = invcloglog(alpha + dot(X_data, betas))
    # p = invloglog(alpha + dot(X_data, betas))
    # p = invcauchit(alpha + dot(X_data, betas))

    # Likelihood
    pm.Bernoulli("y", p=p, observed=y_data)

    # Deviance
    f = pm.Deterministic("f", p**y_data * (1 - p) ** (1 - y_data))
    loglik = pm.Deterministic("loglik", log(f))
    pm.Deterministic("deviance", -2 * sum(loglik))

    # mean prediction
    p_new = pm.Deterministic("p_new", invlogit(alpha + dot(new_data, betas)))

    trace = pm.sample(5000, random_seed=rng)


az.summary(trace, var_names=["alpha", "beta", "deviance", "p_new"])
NUTS[nutpie]: [alpha, beta]

mean sd eti89_lb eti89_ub ess_bulk ess_tail r_hat mcse_mean mcse_sd
alpha -4.4 3.06 -9.4 0.37 3609 4474 1.00 0.051 0.038
beta[0] 0.8 0.74 -0.36 2 4421 5262 1.00 0.011 0.0084
beta[1] 0.96 0.67 -0.069 2.1 4145 5607 1.00 0.01 0.0077
deviance 54.73 2.61 52 60 5289 6529 1.00 0.037 0.046
p_new[0] 0.591 0.091 0.44 0.74 13247 12901 1.00 0.00079 0.00053

3. Caesarean Delivery: Categorical Response#

Table 1 contains grouped data on infection of mothers after a C-section, collected at the Clinical Center of the University of Munich. The response variable has three categories: Infection of type I, Infection of type II, and No infection. For each mother three covariates are collected:

\[\begin{align*} \text{NOPLAN} &= \begin{cases} 1 & \text{C-section was not planned} \\ 0 & \text{Planned} \end{cases} \\ \text{RISK} &= \begin{cases} 1 & \text{Risk factors present} \\ 0 & \text{No risk factors} \end{cases} \\ \text{ANTIB} &= \begin{cases} 1 & \text{Antibiotics given as prophylaxis} \\ 0 & \text{No antibiotics given} \end{cases} \end{align*}\]
  1. Given the covariates, establish a multinomial model, where the outcome “No infection” serves as a baseline.

\[ \text{Table 1: Data on infections for 251 C-sections.} \]
\[\begin{split} \begin{array}{|l|lll|lll|} \hline & \rlap{\text{Planned}} & & & \rlap{\text{Unplanned}} & & \\ \text{Infection} & \text{I} & \text{II} & \text{No} & \text{I} & \text{II} & \text{No} \\ \hline \textbf{Antibiotics} & & & & & & \\ \hspace{1em}\text{Risk factor} & 0 & 1 & 17 & 4 & 7 & 87 \\ \hspace{1em}\text{No risk factor} & 0 & 0 & 2 & 0 & 0 & 0 \\ \hline \textbf{No Antibiotics} & & & & & & \\ \hspace{1em}\text{Risk factor} & 11 & 17 & 30 & 10 & 13 & 3 \\ \hspace{1em}\text{No risk factor} & 4 & 4 & 32 & 0 & 0 & 9 \\ \hline \end{array} \end{split}\]
  1. A new C-section delivery for a mother with covariates \((\text{NOPLAN}, \text{RISK}, \text{ANTIBIO}) = (1, 0, 0)\) is to be evaluated for risks of infection. What are the estimated probabilities of no infection, and type I and II infections?

Hint: Consult 17. Multinomial regression*.

Hide code cell content

import pymc as pm
import arviz as az
import numpy as np
import pytensor.tensor as pt

rng = np.random.default_rng(6420)


# y columns: infection I, infection II, No infection
y = np.array(
    [
        [0, 1, 17],
        [0, 0, 2],
        [11, 17, 30],
        [4, 4, 32],
        [4, 7, 87],
        [0, 0, 0],
        [10, 13, 3],
        [0, 0, 9],
    ]
)

# X columns: planned, risk, antibiotics
X = np.array(
    [
        [0, 1, 1],
        [0, 0, 1],
        [0, 1, 0],
        [0, 0, 0],
        [1, 1, 1],
        [1, 0, 1],
        [1, 1, 0],
        [1, 0, 0],
    ]
)

# add intercept to X
X_aug = np.concatenate((np.ones((X.shape[0], 1)), X), axis=1)
N, P = X_aug.shape
K = y.shape[1]

# new data point, with intercept
new_data = np.array([[1, 1, 0, 0]])


with pm.Model() as m:
    y_data = pm.Data("y", y)
    X_data = pm.Data("X", X_aug)

    _beta = pm.Normal("_beta", mu=0, tau=0.1, shape=(P, K - 1))
    beta = pt.concatenate([_beta, pt.zeros((P, 1))], axis=1)

    eta = pm.math.dot(X_data, beta)
    p = pm.math.softmax(eta, axis=1)

    pm.Multinomial(
        "likelihood",
        n=pm.math.sum(y_data, axis=1),
        p=p,
        observed=y_data,
        shape=X_data.shape,
    )

    eta_new = pm.math.dot(new_data, beta)
    p_new = pm.Deterministic("p_new", pm.math.softmax(eta_new))

    trace = pm.sample(5000, random_seed=rng)

az.summary(trace, var_names="p_new")
NUTS[nutpie]: [_beta]

mean sd eti89_lb eti89_ub ess_bulk ess_tail r_hat mcse_mean mcse_sd
p_new[0, 0] 0.167 0.081 0.06 0.31 13418 11791 1.00 0.00067 0.00055
p_new[0, 1] 0.153 0.073 0.057 0.29 12349 11508 1.00 0.00064 0.00055
p_new[0, 2] 0.68 0.101 0.51 0.83 13233 12139 1.00 0.00087 0.0006

4. Magnesium Ammonium Phosphate and Chrysanthemums#

Walpole et al. (2007) provide data from a study on the effect of magnesium ammonium phosphate on the height of chrysanthemums, which was conducted at George Mason University in order to determine a possible optimum level of fertilization, based on the enhanced vertical growth response of the chrysanthemums. Forty chrysanthemum seedlings were assigned to 4 groups, each containing 10 plants. Each was planted in a similar pot containing a uniform growth medium. An increasing concentration of \(\text{MgNH}_4\text{PO}_4\), measured in grams per bushel, was added to each plant. The 4 groups of plants were grown under uniform conditions in a greenhouse for a period of 4 weeks. The treatments and the respective changes in heights, measured in centimeters, are given in the following table:

Data is available for download in csv format here.

Solve the problem as a Bayesian one-way ANOVA. Use STZ constraints on treatment effects.

  1. Do different concentrations of \(\text{MgNH}_4\text{PO}_4\) affect the average attained height of chrysanthemums? Look at the 95% credible sets for the differences between treatment effects.

  2. Find the 95% credible set for the contrast \(\mu_1 - \mu_2 - \mu_3 + \mu_4\).

Hide code cell content

import pymc as pm
import arviz as az
import pandas as pd
import numpy as np

rng = np.random.default_rng(6420)

data = pd.read_csv("../data/chrysanthemums.csv")

with pm.Model() as m:
    mu0 = pm.Normal("mu_0", mu=0, tau=0.0001)
    tau = pm.Gamma("tau", 0.001, 0.001)

    alpha = pm.ZeroSumNormal("alpha", sigma=10, shape=4)

    mu_1 = mu0 + alpha[0]
    mu_2 = mu0 + alpha[1]
    mu_3 = mu0 + alpha[2]
    mu_4 = mu0 + alpha[3]

    pm.Normal("lik1", mu=mu_1, tau=tau, observed=data["50 g/bu"])
    pm.Normal("lik2", mu=mu_2, tau=tau, observed=data["100 g/bu"])
    pm.Normal("lik3", mu=mu_3, tau=tau, observed=data["200 g/bu"])
    pm.Normal("lik4", mu=mu_4, tau=tau, observed=data["400 g/bu"])

    onetwo = pm.Deterministic("α1-α2", alpha[0] - alpha[1])
    onethree = pm.Deterministic("α1-α3", alpha[0] - alpha[2])
    onefour = pm.Deterministic("α1-α4", alpha[0] - alpha[3])
    twothree = pm.Deterministic("α2-α3", alpha[1] - alpha[2])
    twofour = pm.Deterministic("α2-α4", alpha[1] - alpha[3])
    threefour = pm.Deterministic("α3-α4", alpha[2] - alpha[3])

    part2_contrast = pm.Deterministic(
        "α1-α2-α3+α4", alpha[0] - alpha[1] - alpha[2] + alpha[3]
    )

    trace = pm.sample(5000, random_seed=rng)

az.summary(trace, ci_prob=0.95, var_names="α", filter_vars="like")
NUTS[nutpie]: [mu_0, tau, alpha]

mean sd eti95_lb eti95_ub ess_bulk ess_tail r_hat mcse_mean mcse_sd
α1-α2 -1.78 1.93 -5.5 2 25272 16340 1.00 0.012 0.0092
α1-α3 -2.9 1.95 -6.7 0.95 26097 17128 1.00 0.012 0.0089
α1-α4 -4.67 1.94 -8.5 -0.83 25064 16438 1.00 0.012 0.009
α2-α3 -1.12 1.93 -4.9 2.7 25894 16529 1.00 0.012 0.009
α2-α4 -2.89 1.94 -6.7 0.94 25924 16391 1.00 0.012 0.0088
α3-α4 -1.77 1.93 -5.6 2 25246 16232 1.00 0.012 0.0092
α1-α2-α3+α4 -0.01 2.74 -5.4 5.3 25744 16387 1.00 0.017 0.013

Hide code cell content

az.plot_forest(
    trace,
    var_names="alpha",
    combined=True,
)
<arviz_plots.plot_collection.PlotCollection at 0x3225bbd90>
../_images/e90197cb4a7e1fdd65fb485ddc95b0a1ca8be2c8ee24d3bf5e303067cbb2719d.png

5. Third-degree Burns#

The data for this exercise, discussed in Fan et al. (1995), refer to \(n = 435\) adults who were treated for third-degree burns by the University of Southern California General Hospital Burn Center. The patients were grouped according to the area of third-degree burns on the body. For each midpoint of the groupings “log(area +1),” the number of patients in the corresponding group who survived and the number who died from the burns was recorded:

\[\begin{split} \begin{array}{|c|c|c|} \hline \text{Log(area+1)} & \text{Survived} & \text{Died} \\ \hline 1.35 & 13 & 0 \\ 1.60 & 19 & 0 \\ 1.75 & 67 & 2 \\ 1.85 & 45 & 5 \\ 1.95 & 71 & 8 \\ 2.05 & 50 & 20 \\ 2.15 & 35 & 31 \\ 2.25 & 7 & 49 \\ 2.35 & 1 & 12 \\ \hline \end{array} \end{split}\]

Data is available for download in csv format here.

  1. Fit the logistic regression on the probability of death due to third-degree burns with the covariate \(x = \log(\text{area} + 1)\). What is the deviance?

  2. Using your model, estimate the posterior probability of survival for a person for whom \(\log(\text{area} + 1)\) equals 2.

  3. Repeat (a) with probit and complementary log-log links. In terms of deviance, which model provides the best fit?

Hide code cell content

# Binomial version of solution

import pymc as pm
import arviz as az
import pandas as pd
import numpy as np
from pymc.math import dot, invlogit, invprobit, log, sum, exp
from scipy.special import factorial

rng = np.random.default_rng(6420)


def binom_coeff(n, k):
    return factorial(n) / (factorial(k) * factorial(n - k))


# read data, and calculate n and binomial coefficienct for each row
data = pd.read_csv("../data/thirddegreeburns.csv")
data["n"] = data["Survived"] + data["Died"]
data["binom_coeff"] = binom_coeff(data["n"], data["Survived"])


# Log-log transformation
def invloglog(x):
    return exp(-exp(-x))


with pm.Model() as m:
    # Data
    X_data = pm.Data("X_data", data["Log(area+1)"])
    y_data = pm.Data("y_data", data["Survived"])
    n_data = pm.Data("n_data", data["n"])
    binom_coef_data = pm.Data("binom_coef_data", data["binom_coeff"])

    # Coefficient priors
    alpha = pm.Normal("alpha", mu=0, sigma=1000)
    beta = pm.Normal("beta", mu=0, sigma=1000)

    # Regression
    # p = invlogit(alpha + dot(X_data, beta))
    # p = invprobit(alpha + dot(X_data, beta))
    p = invloglog(alpha + dot(X_data, beta))

    # Likelihood
    pm.Binomial("y", p=p, n=n_data, observed=y_data)

    # Deviance
    f = pm.Deterministic(
        "f", binom_coef_data * (p**y_data * (1 - p) ** (n_data - y_data))
    )
    loglik = pm.Deterministic("loglik", log(f))
    pm.Deterministic("deviance", -2 * sum(loglik))

    # mean prediction
    p_new = pm.Deterministic("p_new", invlogit(alpha + 2 * beta))

    trace = pm.sample(5000, random_seed=rng)

    # another way to find loglik, to check formula above
    # ll = pm.compute_log_likelihood(trace)

az.summary(trace, var_names=["alpha", "beta", "deviance", "p_new"])
NUTS[nutpie]: [alpha, beta]

mean sd eti89_lb eti89_ub ess_bulk ess_tail r_hat mcse_mean mcse_sd
alpha 18.17 1.57 16 21 2152 2263 1.00 0.034 0.024
beta -8.31 0.73 -9.5 -7.1 2146 2336 1.00 0.016 0.011
deviance 32.13 1.98 30 36 4374 4373 1.00 0.033 0.048
p_new 0.8254 0.02 0.79 0.86 3689 5171 1.00 0.00033 0.00023

Hide code cell content

# Binomial version of solution

# First, expand the data to a long format,
# where each row corresponds to a single observation (either survived or died).

data_long = []
for i in range(len(data)):
    for j in range(int(data.iloc[i]["Survived"])):
        data_long.append([data.iloc[i]["Log(area+1)"], 1])
    for j in range(int(data.iloc[i]["Died"])):
        data_long.append([data.iloc[i]["Log(area+1)"], 0])

data_long = pd.DataFrame(data_long)
data_long.rename(columns={0: "Log(area+1)", 1: "Survived"}, inplace=True)

with pm.Model() as m:
    # Data
    X_data = pm.Data("X_data", data_long["Log(area+1)"])
    y_data = pm.Data("y_data", data_long["Survived"])

    # Coefficient priors
    alpha = pm.Normal("alpha", mu=0, sigma=1000)
    beta = pm.Normal("beta", mu=0, sigma=1000)

    # Bernoulli Regression
    # p = invlogit(alpha + dot(X_data, beta))
    # p = invprobit(alpha + dot(X_data, beta))
    p = invloglog(alpha + dot(X_data, beta))

    # Likelihood
    pm.Bernoulli("y", p=p, observed=y_data)

    # Deviance
    f = pm.Deterministic("f", p**y_data * (1 - p) ** (1 - y_data))
    loglik = pm.Deterministic("loglik", log(f))
    pm.Deterministic("deviance", -2 * sum(loglik))

    # mean prediction
    p_new = pm.Deterministic("p_new", invlogit(alpha + 2 * beta))

    trace = pm.sample(5000, random_seed=rng)

az.summary(trace, var_names=["alpha", "beta", "deviance"])
NUTS[nutpie]: [alpha, beta]

mean sd eti89_lb eti89_ub ess_bulk ess_tail r_hat mcse_mean mcse_sd
alpha 18.12 1.58 16 21 2164 2550 1.00 0.034 0.024
beta -8.28 0.74 -9.5 -7.1 2159 2515 1.00 0.016 0.011
deviance 334.27 1.99 330 340 4201 4190 1.00 0.034 0.047

6. Shocks!#

An experiment was conducted to assess the effect of small electrical currents on farm animals, with the eventual goal of understanding the effects of high-voltage powerlines on livestock. The experiment was carried out with seven cows, and six shock intensities, 0, 1, 2, 3, 4, and 5 milliamps (shocks on the order of 15 milliamps are painful for many humans). Each cow was given 30 shocks, five at each intensity, in random order. The entire experiment was then repeated, so each cow received a total of 60 shocks. For each shock the response, mouth movement, was either present or absent. The data as quoted give the total number of responses, out of 70 trials, at each shock level. We ignore cow differences and differences between blocks (experiments).

\[\begin{split} \begin{array}{|c|c|c|c|} \hline \text{Current (ma)} & y & \text n & p \\ \hline 0 & 0 & 70 & 0.000 \\ 1 & 9 & 70 & 0.129 \\ 2 & 21 & 70 & 0.300 \\ 3 & 47 & 70 & 0.671 \\ 4 & 60 & 70 & 0.857 \\ 5 & 63 & 70 & 0.900 \\ \hline \end{array} \end{split}\]

Here, \(y\) is the number of responses, \(n\) is the number of trials, and \(p\) is the proportion of responses.

Data is available for download in csv format here.

As in the exercise on beetles (bliss data), model \(y\) as a function of \(x\) via binary regression with 5 different links and propose the link that minimizes the deviance.

Hide code cell content

import pymc as pm
import arviz as az
import pandas as pd
import numpy as np
from pymc.math import dot, invlogit, invprobit, log, sum, exp, arctan
from scipy.special import factorial

rng = np.random.default_rng(6420)

data = pd.read_csv("../data/shocks.csv")


def binom_coeff(n, k):
    return factorial(n) / (factorial(k) * factorial(n - k))


# read data, and calculate n and binomial coefficienct for each row
data["binom_coeff"] = binom_coeff(
    data["Number of Trials $n$"], data["Number of Responses $y$"]
)


# Complementary log-log transformation
def invcloglog(x):
    return 1 - exp(-exp(x))


# Log-log transformation
def invloglog(x):
    return exp(-exp(-x))


# Cauchit transformation
def invcauchit(x):
    return 0.5 + (1 / np.pi) * arctan(x)


with pm.Model() as m:
    # Data
    X_data = pm.Data("X_data", data["Current (milliamps)"])
    y_data = pm.Data("y_data", data["Number of Responses $y$"])
    n_data = pm.Data("n_data", data["Number of Trials $n$"])
    binom_coef_data = pm.Data("binom_coef_data", data["binom_coeff"])

    # Coefficient priors
    alpha = pm.Normal("alpha", mu=0, sigma=1000)
    beta = pm.Normal("beta", mu=0, sigma=1000)

    # Regression
    # p = invlogit(alpha + dot(X_data, beta))
    # p = invprobit(alpha + dot(X_data, beta))
    # p = invcloglog(alpha + dot(X_data, beta))
    # p = invloglog(alpha + dot(X_data, beta))
    p = invcauchit(alpha + dot(X_data, beta))

    # Likelihood
    pm.Binomial("y", p=p, n=n_data, observed=y_data)

    # Deviance
    f = pm.Deterministic(
        "f", binom_coef_data * (p**y_data * (1 - p) ** (n_data - y_data))
    )
    loglik = pm.Deterministic("loglik", log(f))
    pm.Deterministic("deviance", -2 * sum(loglik))

    trace = pm.sample(5000, random_seed=rng)

    # another way to find loglik, to check formula above
    # ll = pm.compute_log_likelihood(trace)

az.summary(trace, var_names=["alpha", "beta", "deviance"])
NUTS[nutpie]: [alpha, beta]

mean sd eti89_lb eti89_ub ess_bulk ess_tail r_hat mcse_mean mcse_sd
alpha -4.34 0.69 -5.5 -3.3 2956 3097 1.00 0.013 0.01
beta 1.675 0.252 1.3 2.1 2956 3014 1.00 0.0046 0.0037
deviance 34.86 2.07 33 39 5060 5800 1.00 0.031 0.045

7. Binary Regression and IOP#

Laser refractive surgery often decreases Intraocular Pressure (IOP) and may lead to hypotony (clinically significant low IOP that may lead to corneal decompensation, accelerated cataract formation, maculopathy, and discomfort). An investigator wished to determine whether the post-operative IOP in patients after laser refractive surgery was related to the residual thickness of the cornea.

In a sample of 140 patients who had undergone laser surgery, post-operative IOP and the thickness of the cornea were measured. The dataset is provided in the startup file iop2.odc which consists of two columns:

  • Indicator of low IOP (IOP < 10)

  • Central corneal thickness (in micrometers)

  1. Fit the logistic regression with cornea thickness as the predictor of incidence of low IOP.

  2. For a person who had a refractive surgery with residual thickness of cornea of 420 micrometers, what is the risk of a low IOP.

  3. Compare deviances for two links: logit (as in (a)), and probit. Which link provides better fit?

Data is available for download in csv format here.

Hide code cell content

import pymc as pm
import arviz as az
import pandas as pd
import numpy as np
from pymc.math import dot, invlogit, invprobit, log, sum

rng = np.random.default_rng(6420)


def standardize(X_df: pd.DataFrame) -> pd.DataFrame:
    """
    Standardize input variables by 2 std dev.

    See https://stat.columbia.edu/~gelman/research/published/standardizing7.pdf.
    """
    # find and store means and std, then standardize
    means = X_df.mean(axis=0)
    stdevs = X_df.std(axis=0)
    X_standardized = (X_df - means) / (2 * stdevs)

    return X_standardized


data = pd.read_csv("../data/iop.csv")

# default NUTS ssampler diverges unless data is standardized. Other samplers work fine with non-standardized data
X_std = standardize(data["Thickness"])

with pm.Model() as m:
    # Data
    # X_data = pm.Data("X_data", X_std)
    X_data = pm.Data("X_data", data["Thickness"])
    y_data = pm.Data("y_data", data["LowIOP"])

    # Coefficient priors
    alpha = pm.Normal("alpha", mu=0, sigma=1000)
    beta = pm.Normal("beta", mu=0, sigma=1000)

    # Bernoulli Regression
    # p = invlogit(alpha + dot(X_data, beta))
    p = invprobit(alpha + dot(X_data, beta))

    # Likelihood
    pm.Bernoulli("y", p=p, observed=y_data)

    # Deviance
    f = pm.Deterministic("f", p**y_data * (1 - p) ** (1 - y_data))
    loglik = pm.Deterministic("loglik", log(f))
    pm.Deterministic("deviance", -2 * sum(loglik))

    # mean prediction
    p_new = pm.Deterministic("p_new", invlogit(alpha + 420 * beta))

    # trace = pm.sample(5000)
    # trace = pm.sample(5000,nuts_sampler="numpyro")
    # trace = pm.sample(5000,nuts_sampler="blackjax")
    trace = pm.sample(5000, nuts_sampler="nutpie", random_seed=rng)

az.summary(trace, var_names=["alpha", "beta", "deviance"])
NUTS[nutpie]: [alpha, beta]

mean sd eti89_lb eti89_ub ess_bulk ess_tail r_hat mcse_mean mcse_sd
alpha 7.47 1.86 4.6 11 2048 2331 1.00 0.041 0.029
beta -0.0172 0.0039 -0.024 -0.011 2043 2389 1.00 8.7e-05 6.1e-05
deviance 134.08 2.03 130 140 4304 4205 1.00 0.034 0.046

8. Negative Binomial as a Gamma Mixture of Poissons#

Implement this model, which recreates a negative binomial regression as a gamma mixture of Poissons.

\[\begin{align*} y_i | \lambda_i &\sim \text{Poisson}(\lambda_i) \\ \lambda_i | \mu_i, \alpha &\sim \text{Gamma}(\alpha, \frac{\alpha}{\mu_i}) \\ \mu_i &= \exp(\beta_0 + \beta_1 x_i) \\ \beta_0 &\sim \mathcal{N}(0, 10^4) \\ \beta_1 &\sim \mathcal{N}(0, 10^4) \\ \alpha &\sim \text{Uniform}(0.01, 100) \end{align*}\]

Here’s the data:

x = np.array([12.2, 14.2, 9.8, 16.3, 20.1, 18.4, 22.7, 20.2, 21.4, 33.0, 30.5])
y = np.array([5, 6, 6, 7, 6, 8, 11, 10, 18, 20, 22])

Hide code cell content

import pymc as pm
import arviz as az
import pandas as pd
import numpy as np

rng = np.random.default_rng(6420)


x = np.array([12.2, 14.2, 9.8, 16.3, 20.1, 18.4, 22.7, 20.2, 21.4, 33.0, 30.5])
y = np.array([5, 6, 6, 7, 6, 8, 11, 10, 18, 20, 22])

with pm.Model() as m:
    X_data = pm.Data("X_data", x)
    y_data = pm.Data("y_data", y)

    β0 = pm.Normal("β0", mu=0, tau=0.0001)
    β1 = pm.Normal("β1", mu=0, tau=0.0001)
    α = pm.Uniform("α", 0.01, 100)

    μ = pm.math.exp(β0 + β1 * X_data)

    λ = pm.Gamma("λ", α, α / μ)

    likelihood = pm.Poisson(
        "likelihood", mu=λ, observed=y_data, shape=y_data.shape[0]
    )

    trace = pm.sample(5000, random_seed=rng)
    # trace = pm.sample(5000,nuts_sampler="nutpie")

az.summary(trace, var_names=["α", "β0", "β1"])
NUTS[nutpie]: [β0, β1, α, λ]

mean sd eti89_lb eti89_ub ess_bulk ess_tail r_hat mcse_mean mcse_sd
α 58.3 25.4 17 96 4621 5953 1.00 0.36 0.17
β0 0.95 0.346 0.39 1.5 2557 3960 1.00 0.0068 0.005
β1 0.0664 0.0148 0.043 0.09 2422 3788 1.00 0.0003 0.00022

9. Sex of Diamond-backed Terrapins and Incubation Temperature#

Temperature-dependent sex determination, observed in some reptiles and fish, is a type of environmental sex determination in which the temperatures experienced during embryonic development determine the sex of the offspring. Data on the relationship between the ratio of male/female diamond-backed terrapins (Malaclemys terrapin) and incubation temperature are reported by Burke and Calichio [2014].

  1. Develop a binary regression model for both logit and cloglog links.

  2. Which link gives smaller deviance?

  3. Predict the probability of a female terrapin for a temperature of 29°C, using both models.

Data is available for download in csv format here.

Hide code cell content

import pymc as pm
import arviz as az
import pandas as pd
import numpy as np
from pymc.math import dot, invlogit, log, sum, exp
from scipy.special import factorial

rng = np.random.default_rng(6420)


def binom_coeff(n, k):
    return factorial(n) / (factorial(k) * factorial(n - k))


data = pd.read_csv("../data/terrapins.csv")
data["binom_coeff"] = binom_coeff(data["Total"], data["Female"])


# Complementary log-log transformation
def invcloglog(x):
    return 1 - exp(-exp(x))


with pm.Model() as m:
    # Data
    X_data = pm.Data("X_data", data["Temp"])
    y_data = pm.Data("y_data", data["Female"])
    n_data = pm.Data("n_data", data["Total"])
    binom_coef_data = pm.Data("binom_coef_data", data["binom_coeff"])

    # Coefficient priors
    alpha = pm.Normal("alpha", mu=0, tau=0.001)
    beta = pm.Normal("beta", mu=0, tau=0.001)

    # Regression
    p = invlogit(alpha + dot(X_data, beta))
    # p = invcloglog(alpha + dot(X_data, beta))

    # Likelihood
    pm.Binomial("y", p=p, n=n_data, observed=y_data)

    # Deviance
    f = pm.Deterministic(
        "f", binom_coef_data * (p**y_data * (1 - p) ** (n_data - y_data))
    )
    loglik = pm.Deterministic("loglik", log(f))
    pm.Deterministic("deviance", -2 * sum(loglik))

    # mean prediction
    p_new = pm.Deterministic("p_new", invlogit(alpha + 29 * beta))

    trace = pm.sample(5000, random_seed=6420)
    # trace = pm.sample(5000, nuts_sampler="nutpie")

    # another way to find loglik, to check formula above
    # ll = pm.compute_log_likelihood(trace)

az.summary(trace, var_names=["alpha", "beta", "deviance", "p_new"])
NUTS[nutpie]: [alpha, beta]

mean sd eti89_lb eti89_ub ess_bulk ess_tail r_hat mcse_mean mcse_sd
alpha -32.1 4.4 -39 -25 2519 2661 1.00 0.088 0.064
beta 1.14 0.158 0.9 1.4 2515 2656 1.00 0.0032 0.0023
deviance 19.82 1.9 18 23 3799 4124 1.00 0.033 0.048
p_new 0.725 0.052 0.64 0.81 6250 7872 1.00 0.00065 0.00046